I'm always super interested in expanding the frontier of learned compression. The current methods we use are derived from VAEs (equivalence shown in [3]) and use GANs to improve perceptual quality but in this blog I explore how diffusion models could be used for compression.
The feasibility of any method we explore in a learned compression pipeline hinges on the complexity of that method. Since decode and sometimes encode are performed on battery constrained edge devices, the scope of a new method to add compute is very limited, often 1-2KMACs/px. As a result training time improvements are favoured over encode/decode. In this blog though, we'll go against this advice and augment our decoder with a denoising diffusion model.
Intro to Diffusion Models
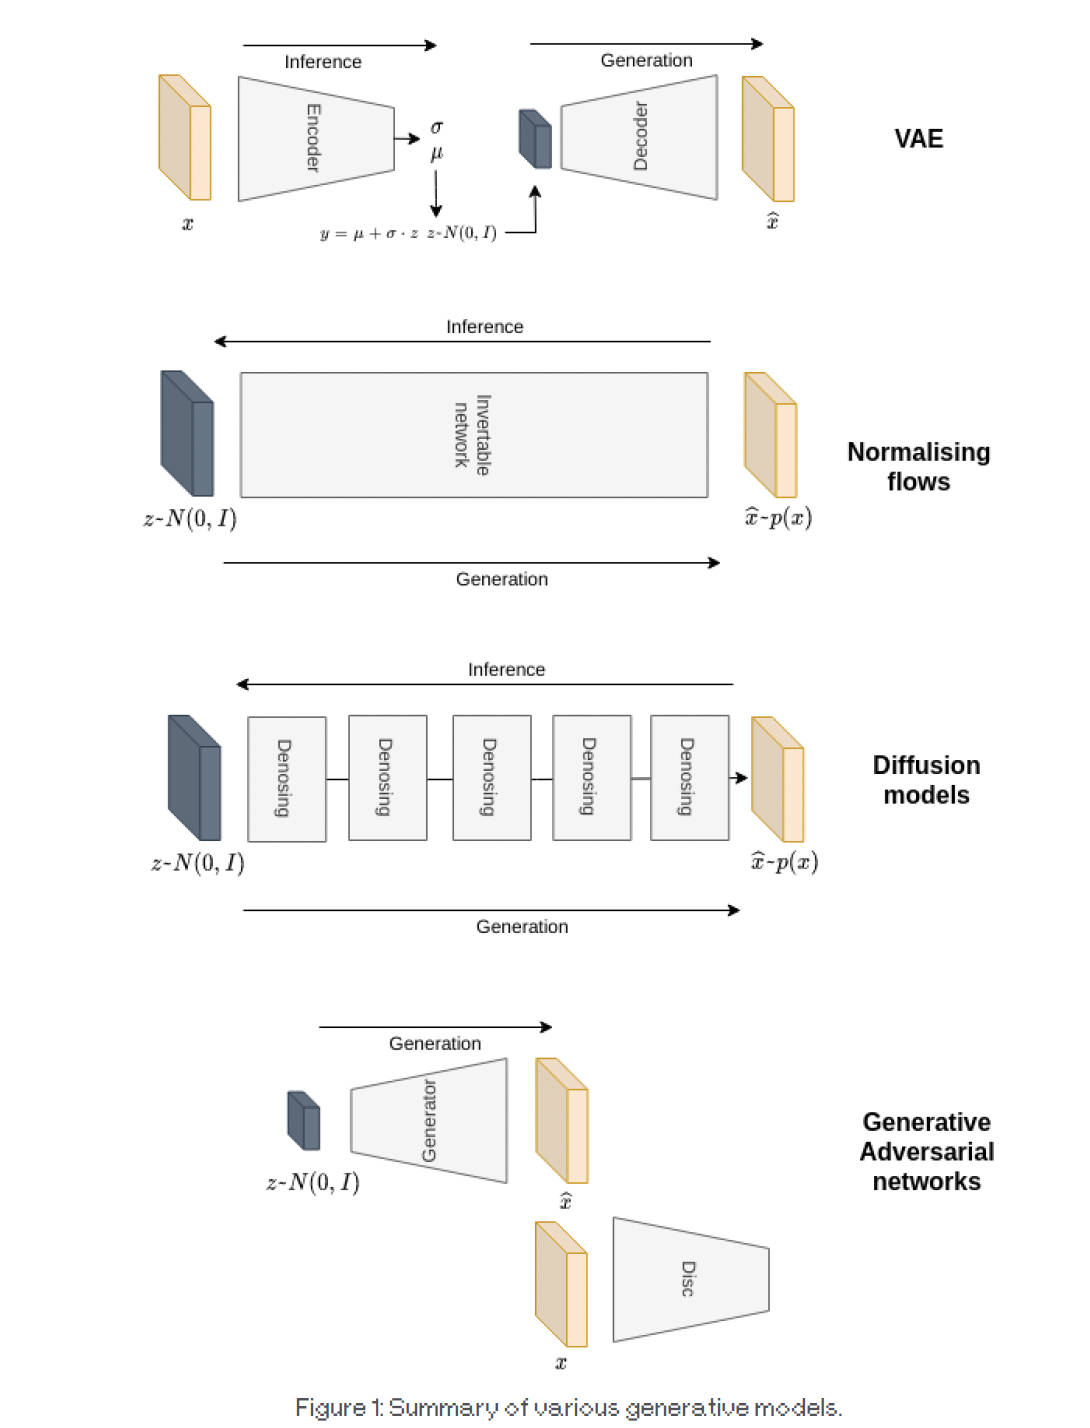
Before we dive into diffusion models, let's summarise the main methods for generating from a distribution currently available to us, and see how diffusion models [1, 2] look compared to them. This is shown in Figure 1.
The forward process
The forward step in a diffusion model consists of adding small amounts of Gaussian noise to our image (which is sampled from our data distribution), until it looks like a Gaussian sample from . We define a number of steps we want to achieve this transition in, and at each step, we add noise with a variance we pre-set (we call this the variance schedule). Since each transition depends only on the present state, the forward process is Markovian and can be written as:
Here, is our variance at time step . As well as adding noise, we also scale down the previous sample by which is required if we are to bound the variance of in the limit of a standard normal. This will be graphically shown later.
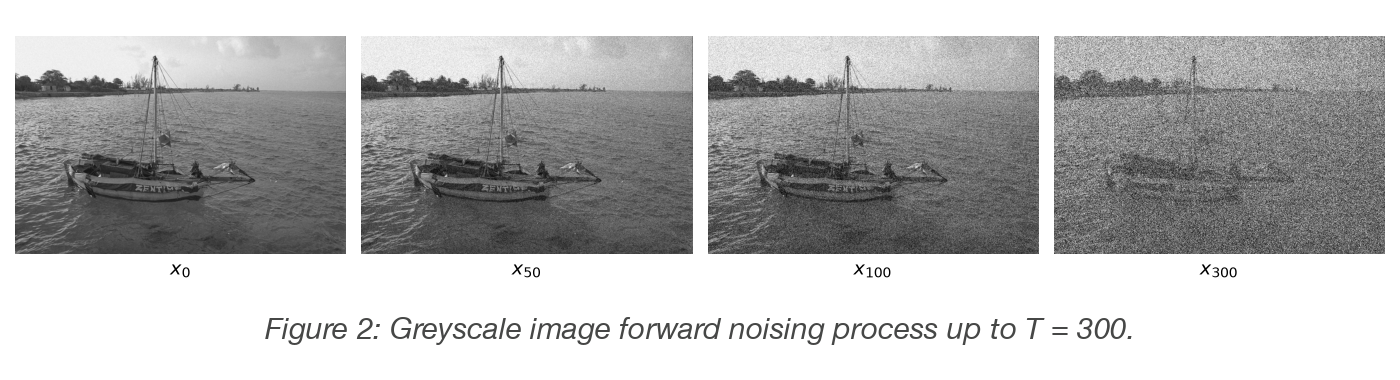
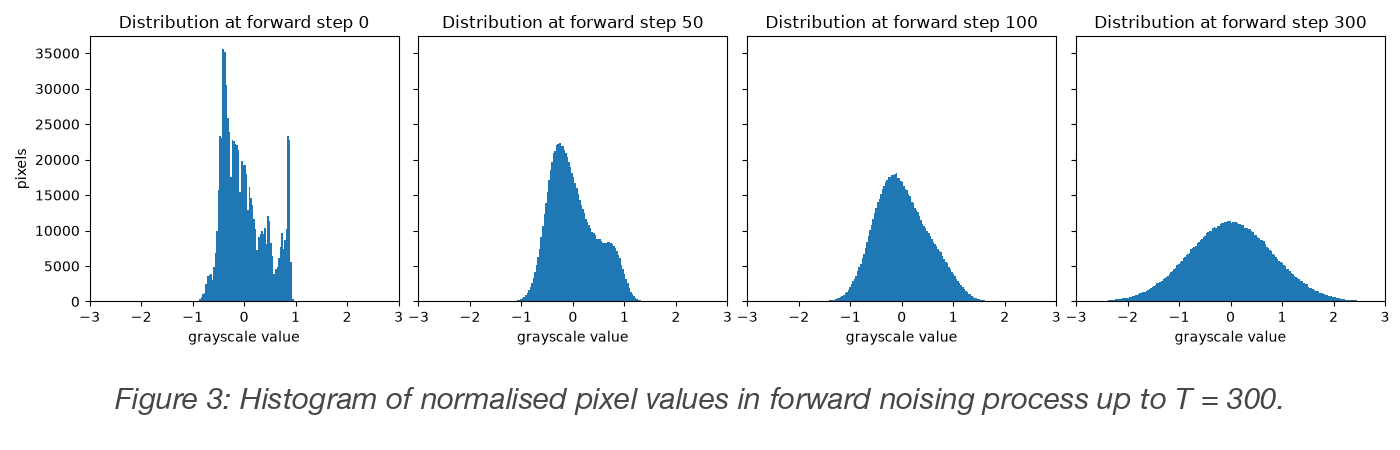
Now, let's see what this means in practice. Let's take an image from the Kodak dataset, and define a variance schedule over steps, starting at and ending at . Figures 2 and 3 below show a grey scale image and its grey value pixel distribution.
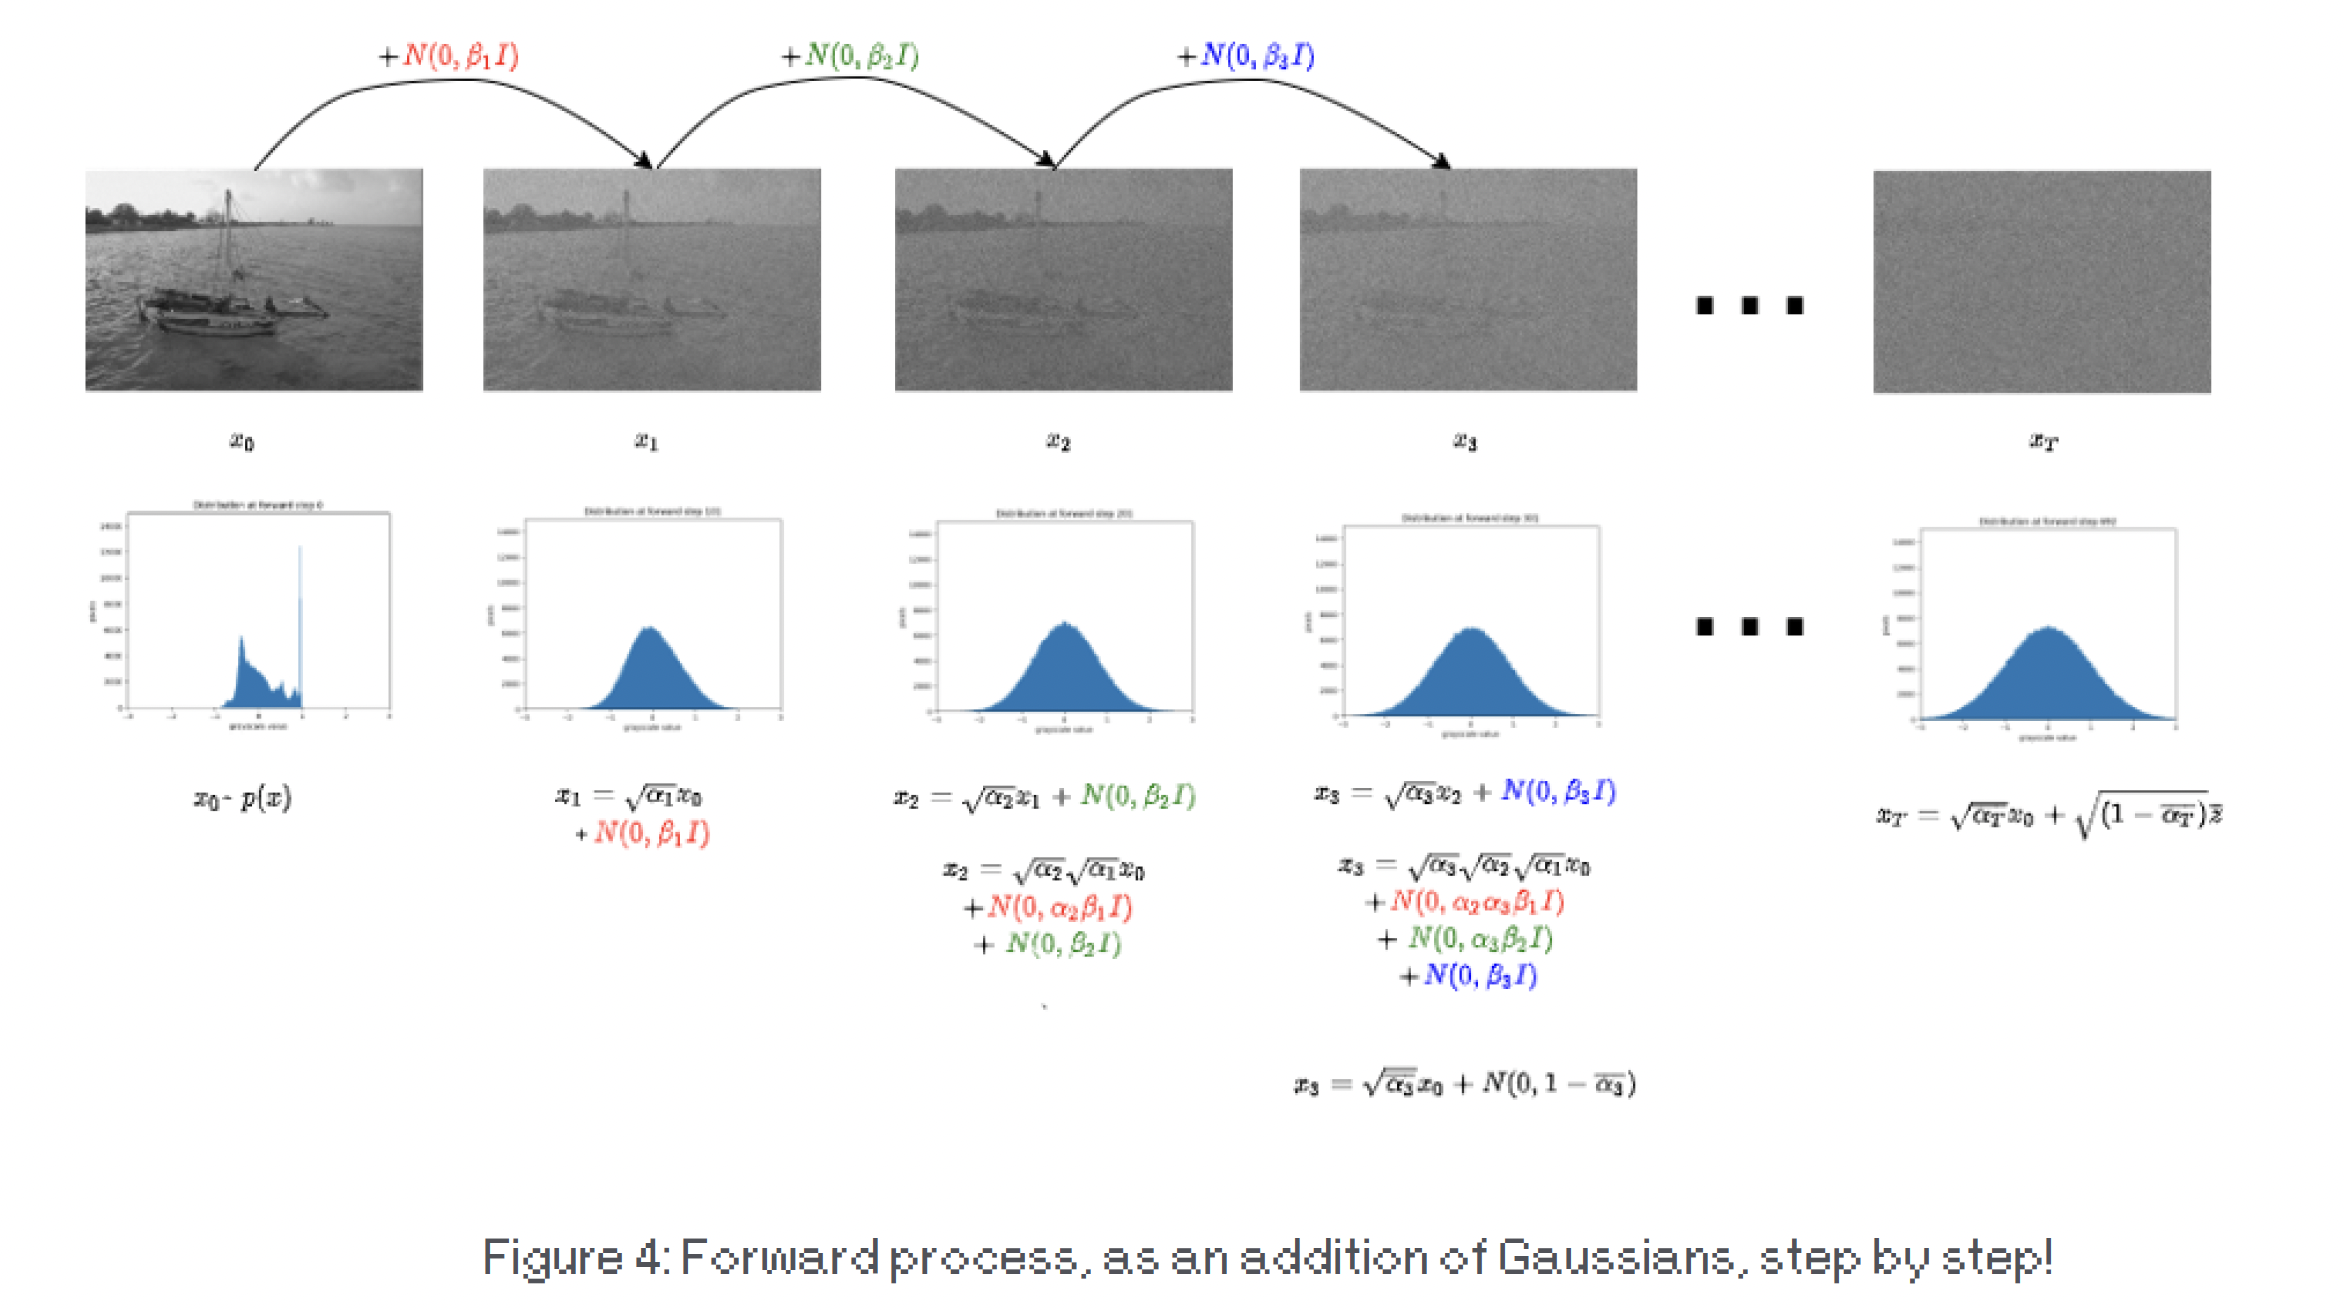
Let's have a closer look at what is actually happening in the forward noising process and some of its useful properties. Essentially, at each step we are adding small amounts of Gaussian noise with a particular variance to the sample from the previous step, , while scaling it down with . To help with notation, let's write . Figure 4 shows the forward step diagrammatically.
Figure 4 shows that at any point in the forward process, we can break down the current sample into two terms:
The initial data sample we are noising ( from ) and a cumulative product of scaling coefficients for , square root of (which depends on the time step we are on and the self-defined variance schedule)
A set of mean-zero Gaussians with different scales where the scales depend on the current time step and self-defined variance schedule. Using the properties of Gaussians, we can combine all these zero-mean Gaussians into one Gaussian with a particular variance, which is just the sum of the variances of all the (scaled) Gaussians up to that point and takes the form . A simple derivation of this is shown later.
Scaling x
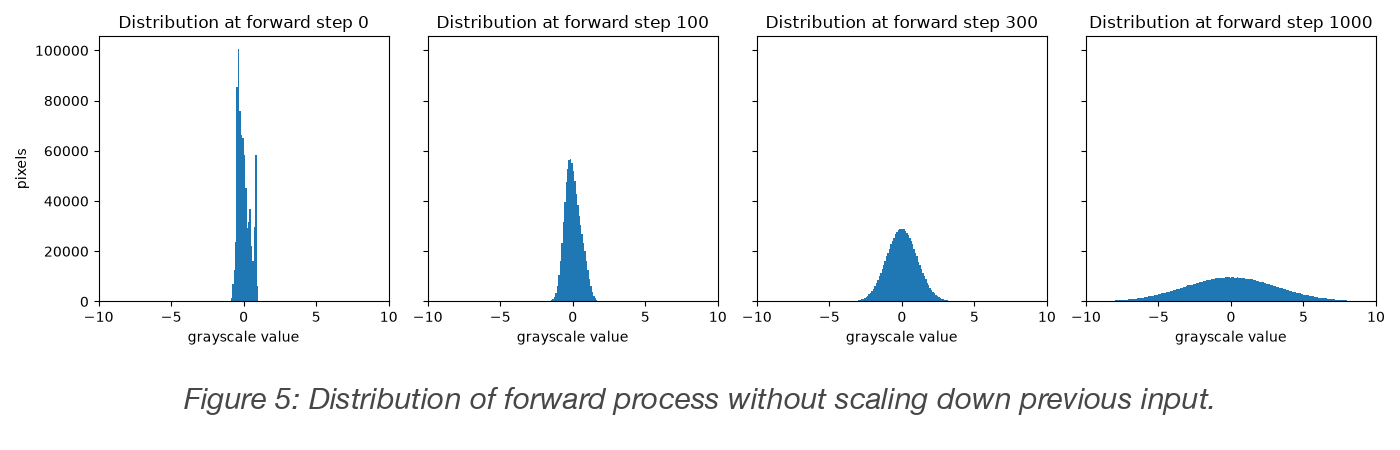
Why do we need to scale down the previous input at each step by ? Well, let's have a look at what happens if we don't. Figure 5 shows the same process as Figure 4, but where the is not scaled down by . We observe that the variance of the distribution continues to grow, so it keeps getting wider, which means it is not an .
Sampling at an arbitrary time step
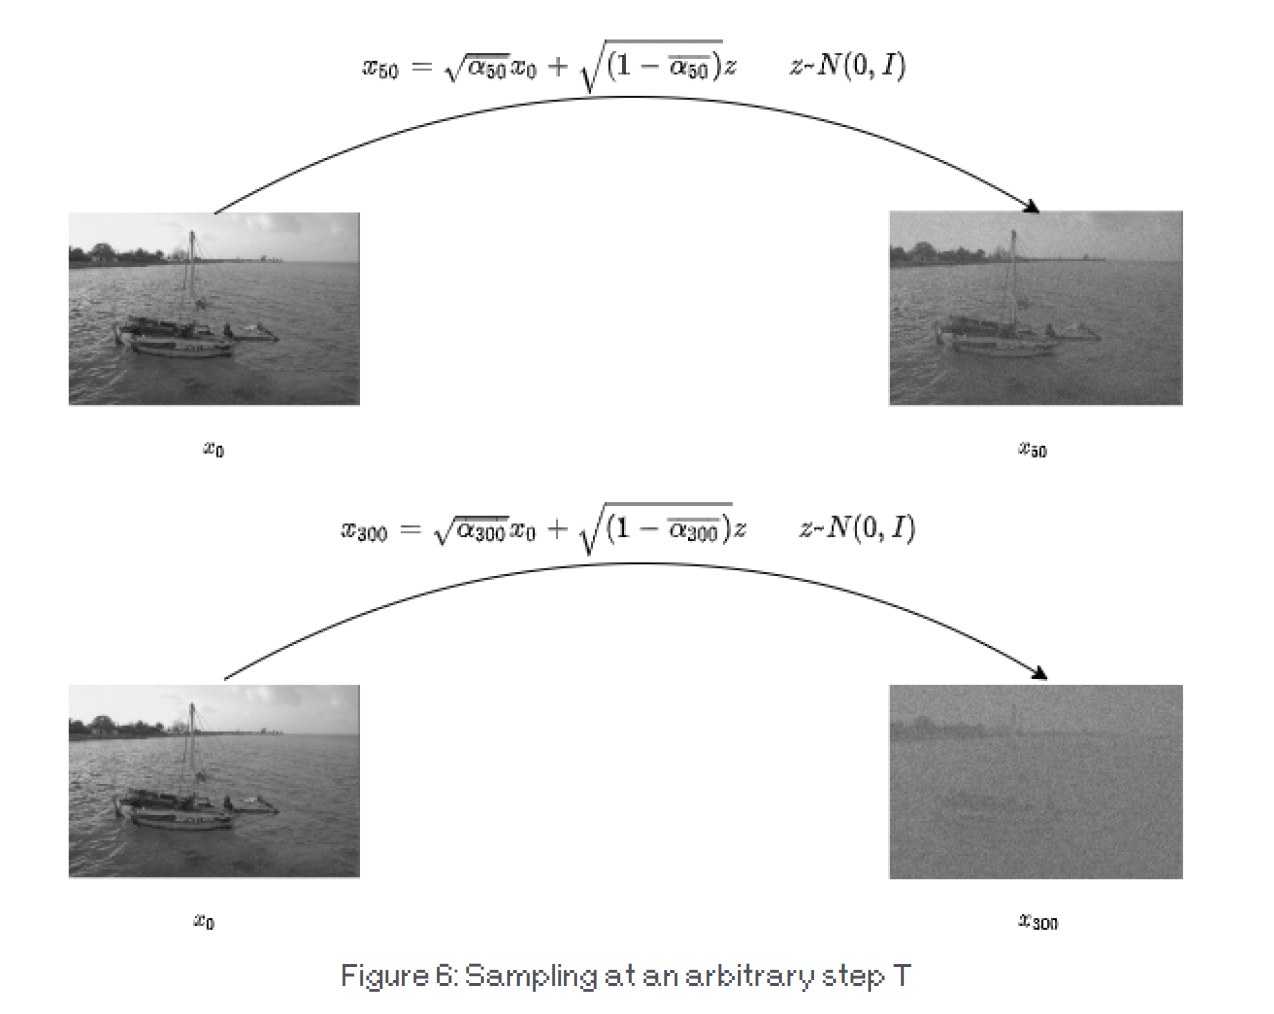
Since we are adding a lot of Gaussians to a sample, this affords us the nice properties Gaussians bring with them. One useful property we can extract from this is the ability to sample a noisy at any time step (without having to go through the entire forward process up to that point), given an . This is because we define the variance schedule and therefore, at any time steps, we know all the Gaussian samples that were added to to get that particular noisy . Figure 4 already shows this, but here we provide more detail.
For any :
Here, is a sample from a standard normal. The figure below demonstrates how we can jump from directly to and through combining all the variances of the Gaussians in the chain up to those points. This is an extremely useful property and will help us in training as we shall see later.
The reverse process
The learned reverse process is written as:
Like variational inference, is an approximate distribution for the reverse of our forward process, , and we close the gap between the two using KL-divergence.
is generally intractable; however, it can be shown to be tractable when conditioned on . This results in the following formulation of what we call the forward process posterior:
where the posterior mean is:
This can be derived with (2.116) in Bishop's book. Therefore, if we can predict our posterior mean
and our variance (which can easily be computed as all terms are always known), we should be able to sample from our reverse posterior .
If we have a look at this mean, during the reverse/sampling process, we know and as these are self-defined. is the current step we are on, which we know too (since we start with a sample from ). The only term we do not know at sampling time is . This is what we need a neural network to help us predict. We can train a network to directly predict this, given and as inputs, however, this is empirically shown not to work too well [1], and a better method is to do the following:
We know from the forward process that:
where which we can rearrange to get . Once is predicted, this gives an approximation of , say :
We can plug this formula in for in the forward process posterior definition to obtain the reverse sampling step:
This leaves us with the unknown noise sample from a standard normal which we need to predict; all other terms are known. We can define a neural network to predict this term:
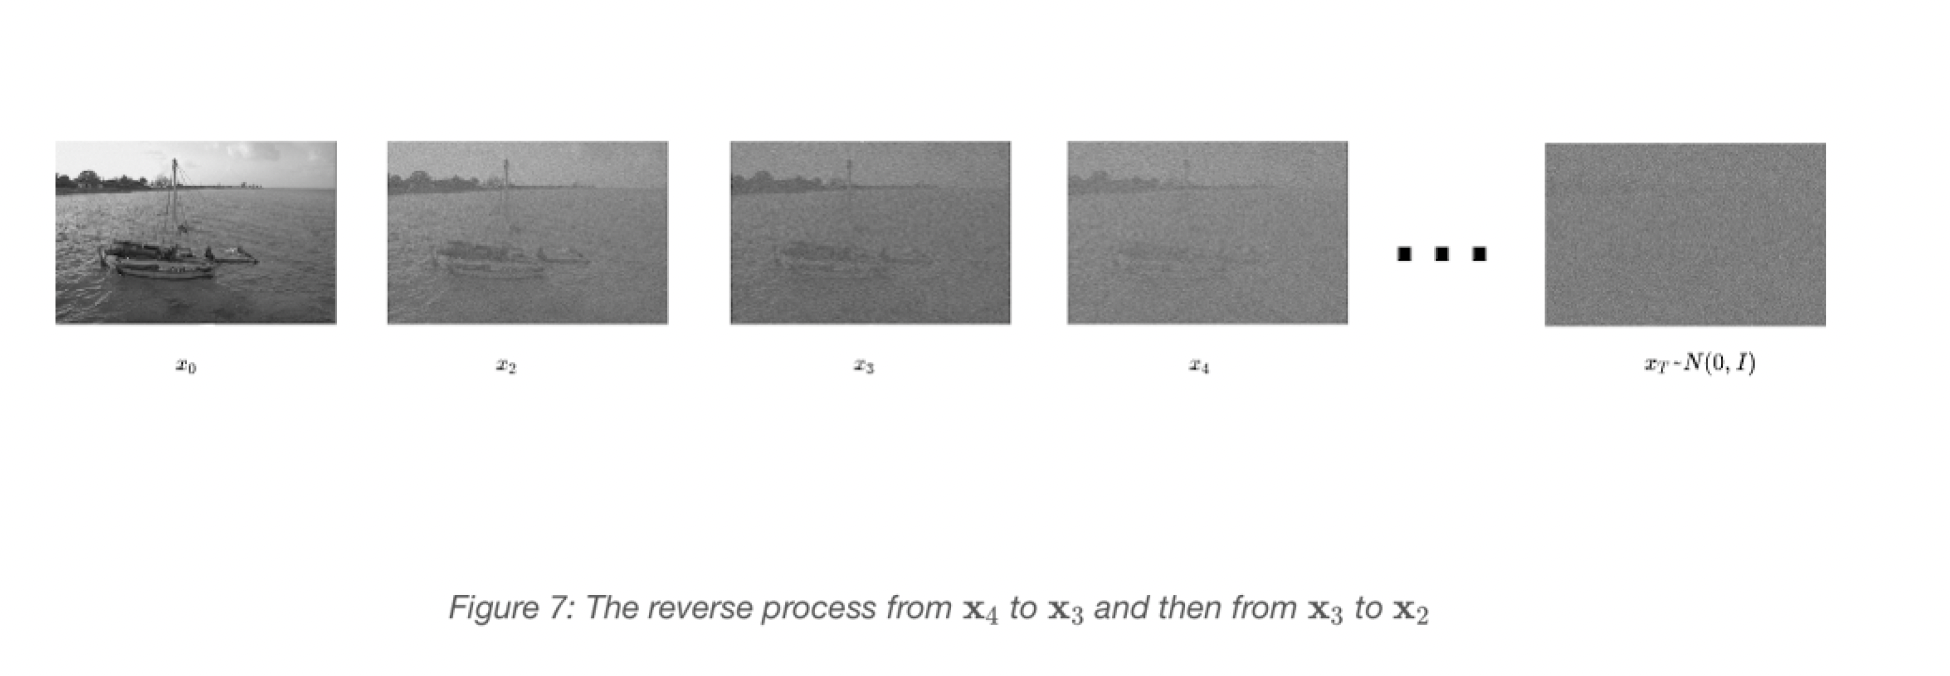
Once we have estimated , we can compute , after which we can predict and sample the . Then we can repeat this process, until we get to which is our sample from the distribution. Figure 7 shows the samples this process passes through, from on the right back to on the left, for example from to and then to .
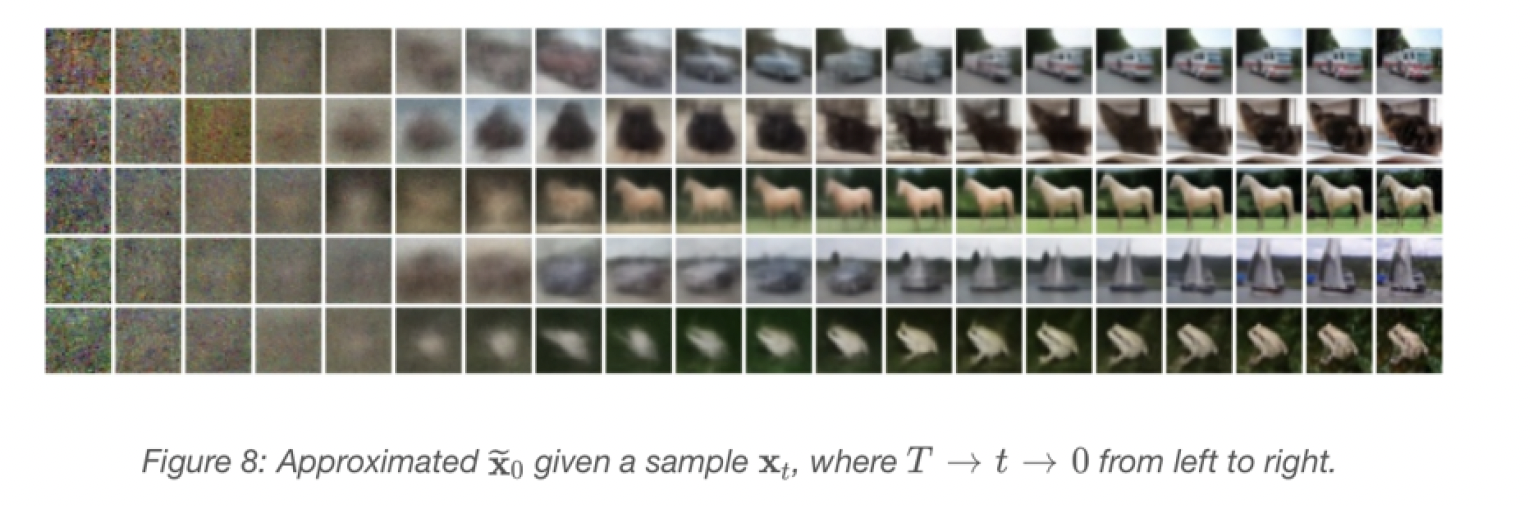
What does look like at each time step? That depends on where you are; if you are quite early in the chain, it looks like noise with some structure. If you are close to the end of the chain, it almost looks like an image. An example is shown in Figure 8, taken from the DDPM paper.
Training
The loss function is a maximisation problem of the variational lower bound on the log-likelihood of the data:
This can be reduced to a sum of KL-divergences between and . Since both are Gaussian, this is just a KL between two Gaussians. Working through this, we can end up with a simplified loss term (we need to drop some scaling constants that arise when we do the KL between the Gaussians), corresponding to a weighted variational lower bound:
This is the simplified objective we can use to train our denoising function , which is generally selected to be some sort of U-Net architecture. What this denoising function learns during training is the noise that was added to samples from the dataset to noise them. Once it is fully trained, it can then be used to remove that noise. The training process is then extremely simple and is performed as below:
We sample an image from our dataset and select a random time step
We sample an instance of noise:
We generate the noisy sample at this time step using the sampled noise and variance schedule (see forward process section)
We feed this and to our denoising function to approximate
We use an L2-metric to compute a loss between and
Conditional compression denoising decoder
Is there a way we could use diffusion models in our compression pipeline? Can they be used for explicit likelihood or implicit distribution matching?
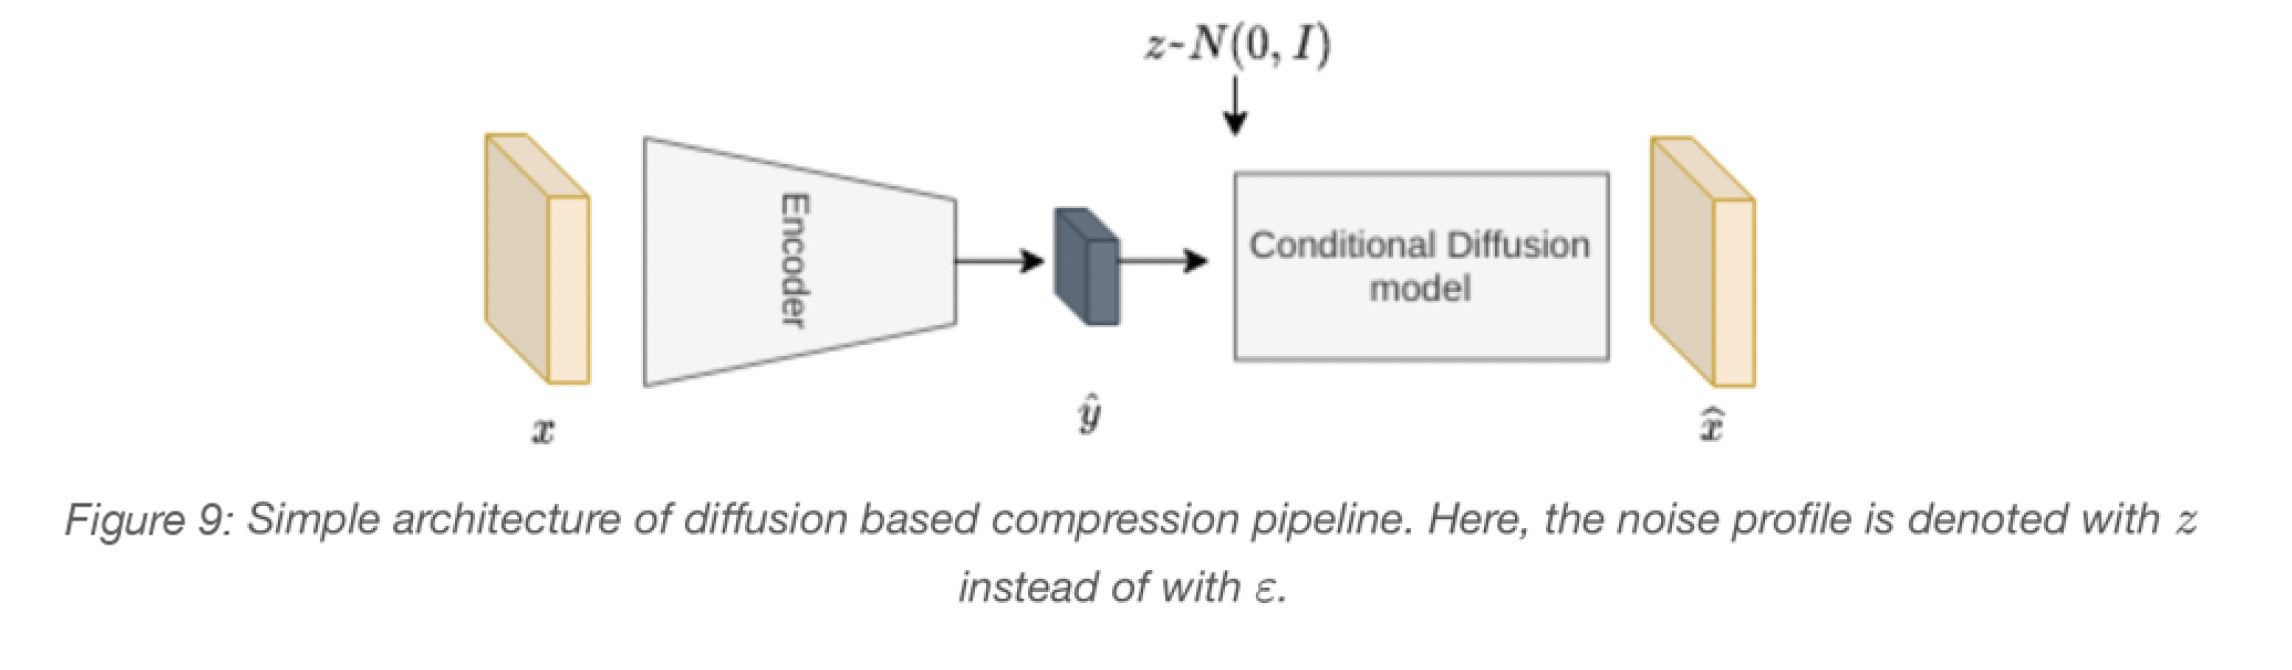
An immediate idea would be to replace our decoder with a conditional diffusion model where we condition the diffusion process on the quantised latent space. This would enable conditional image generation, trained with the rate as usual and the denoising loss in place of the distortion. As the denoising loss is a bound on the likelihood, this is the explicit likelihood route.
There are a few changes that we would need to consider for the pipeline. Let's break them down into architecture, training and inference.
Architecture
Until the decoder, our architecture can remain the same, however, we would then need to upsample our quantised latent space to the image scale (diffusion models work on the image scale).
We need to define a function , which empirically is shown to work best as a U-Net architecture. The input of the U-Net will need to be the noisy image concatenated with the upsampled latent space, , along with the time step .
The training
The training function we minimise now becomes:
where has an additional input to force it to be conditional, is the rate of and trades the rate off against the denoising loss. Note that the decoder then produces a plausible image given rather than the one closest to , so fidelity (e.g. PSNR) is not directly controlled.
The inference
The encoding works exactly the same, but the decoding differs. After the is produced, we sample , and perform the computation of the reverse process (Figure 7) for each of the steps to get our final output .
I ran the above model and it produced promising results on the first iteration. I have high hopes for the compression performance, but the largest concern is with execution time: decoding runs the U-Net once per step, times, far beyond the 1-2KMACs/px budget mentioned above. We'd need to see a lot more algorithmic progress in diffusion decoders to enable efficient decoding.
Further reading:
[1] Ho, Jonathan, Ajay Jain, and Pieter Abbeel. "Denoising diffusion probabilistic models." Advances in Neural Information Processing Systems (2020). https://arxiv.org/abs/2006.11239
[2] Sohl-Dickstein, Jascha, Eric Weiss, Niru Maheswaranathan, and Surya Ganguli. "Deep unsupervised learning using nonequilibrium thermodynamics." International Conference on Machine Learning. PMLR, 2015. https://arxiv.org/abs/1503.03585
[3] Ballé, Johannes, David Minnen, Saurabh Singh, Sung Jin Hwang, and Nick Johnston. "Variational image compression with a scale hyperprior." International Conference on Learning Representations (2018). https://arxiv.org/abs/1802.01436